Context Engineering Is the New Prompt Engineering
Prompts got cheap; context is the bottleneck. Stale context, lost-in-the-middle effects, and live data decide if your agent ships.
Prompt engineering had a good run. Most of my failures this year turned out to be about context instead. Feed an agent a pile of stale, scattered, half-relevant material and it will hallucinate through your architecture with total confidence, in eloquent structured prose. When that happened to me, my first move was to go shopping for a smarter model. The model was fine. The context was rotting.
Research keeps pointing the same way. Models skip information buried in the middle of long inputs, the “lost in the middle” effect, and agents working without live data hallucinate roughly 35% more on anything time-sensitive. Labs keep shipping bigger windows as if volume were the answer. A bigger haystack does not help if the needle rots.
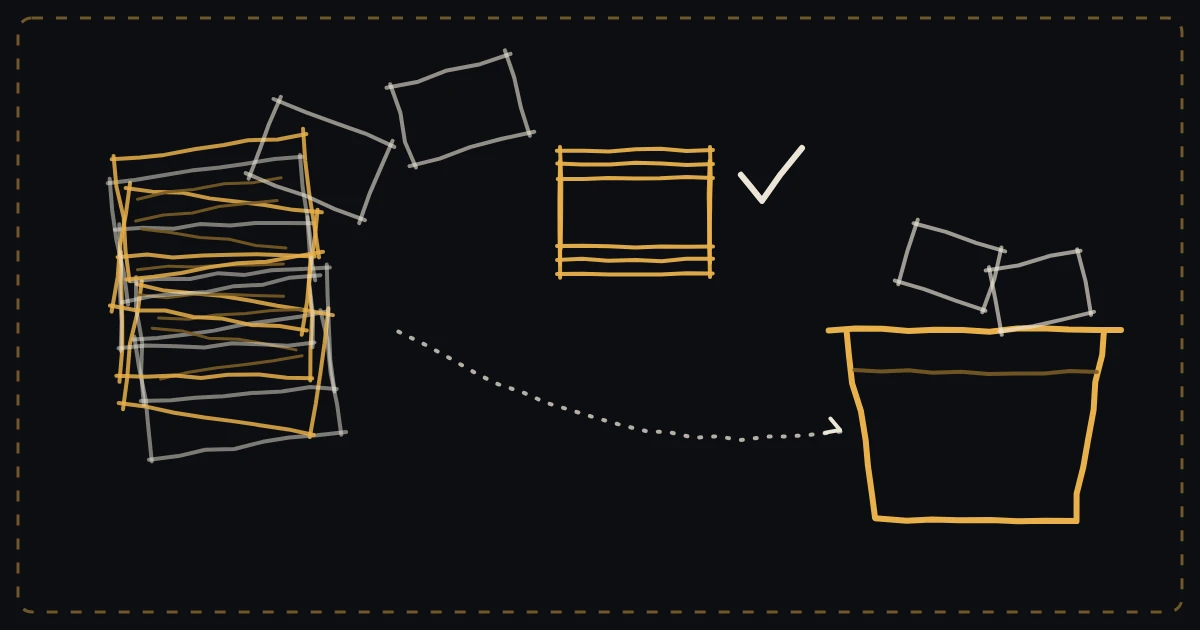
The teams getting real production leverage treat context the way they treat their databases: fresh, relevant, scoped, pruned. Retrieval, tool output, memory, instructions, each one gets curated instead of dumped. In the pipelines I run, the boring cleanup pass before a job does more than any model upgrade I have tried.
Honestly, data hygiene turned out to be the highest-leverage work in the stack, and it is about as glamorous as it sounds.
Before you swap the model, audit what the model is reading.